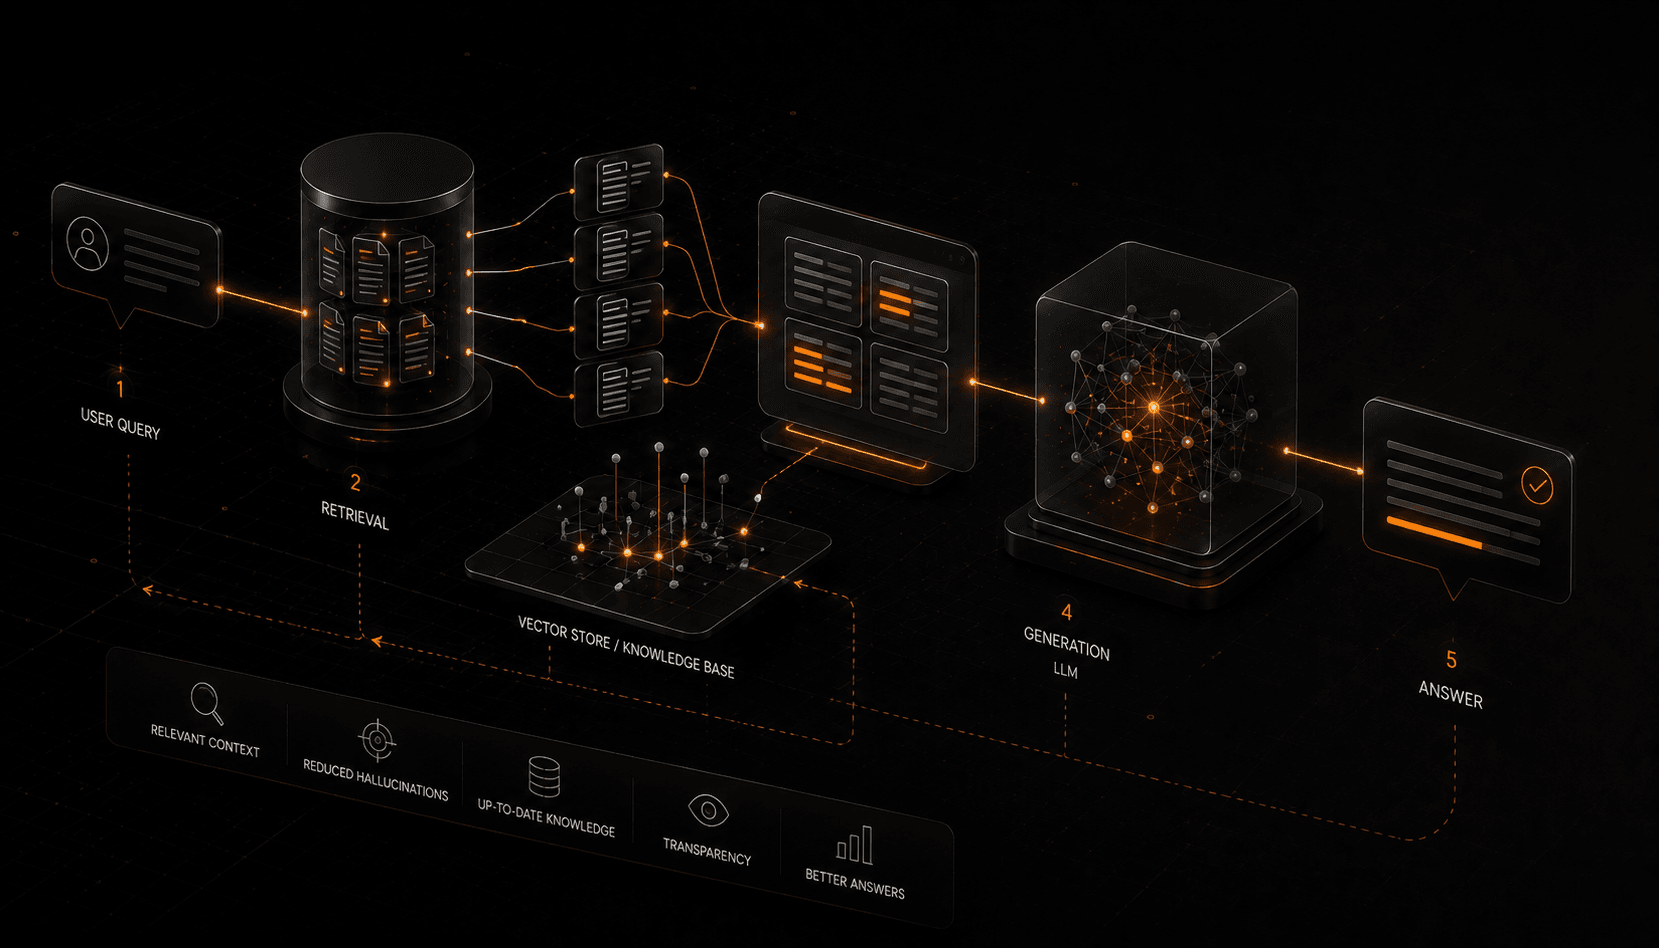
"Agent" has become the most overloaded word in AI, so let me strip it down to what it actually is: a model in a loop that can call tools and read back the results. The model proposes an action, your code runs it, the output is fed back in, and the loop repeats until the task is done or a budget runs out. That's it. Once you see that shape, the mystique drops away and it becomes an engineering problem.
Tools are the whole game
Tools are the whole game. A model on its own can only produce text; give it a search, a run_query, a read_file, and suddenly it can act on the world. The skill isn't prompting — it's designing tools with tight, honest contracts: clear names, typed inputs, and error messages the model can actually recover from. A tool that fails with a vague string teaches the model nothing; one that says exactly what went wrong lets it correct course on the next turn.
Written out, the "agent" everyone is mystified by is barely a dozen lines of control flow:
# An agent is a model in a loop with tools — nothing more exotic than this.
state = init(task)
for _ in range(MAX_STEPS):          # always bound the loop
    action = model.propose(state)   # model picks a tool + arguments
    if action.is_final:
        return action.answer
    result = tools.run(action)      # your code executes it
    state = state.append(result)    # feed the result back in
raise BudgetExceeded                # fail loudly — never loop forever
Bounding the loop
The loop is where reliability is won or lost. Every iteration spends tokens and latency and can compound an earlier mistake, so I bound it deliberately — a maximum step count, a token budget, and an unambiguous stop condition. An agent that can loop forever isn't a feature, it's a bug waiting for a production incident.
Verify, don't just generate
Verification matters more than generation. The dangerous failure mode isn't a model refusing to act; it's acting confidently on a wrong assumption. So the patterns worth reaching for are the ones that check work: a deterministic test or a second model that verifies a step before it's committed, and tools that fail loudly instead of returning plausible-looking garbage.
Start smaller than you think
Start smaller than you think you need to. A lot of problems branded "agentic" are better served by a fixed pipeline of two or three model calls than by an open-ended loop. Reach for the loop only when the number of steps genuinely can't be known ahead of time — and even then, keep a human in the approval path for anything irreversible.
Sources & further reading
- Yao et al., ReAct: Synergizing Reasoning and Acting in Language Models (2022) — the reason-then-act loop that underpins most agent frameworks.
- Schick et al., Toolformer: Language Models Can Teach Themselves to Use Tools (2023) — models learning to call external tools.
- Anthropic, Building Effective Agents (2024) — when to reach for a loop vs. a fixed workflow.
Editorial note — A framing / opinion piece on established patterns (tool use, bounded loops, verification). No specific product, framework, or benchmark claims are made.