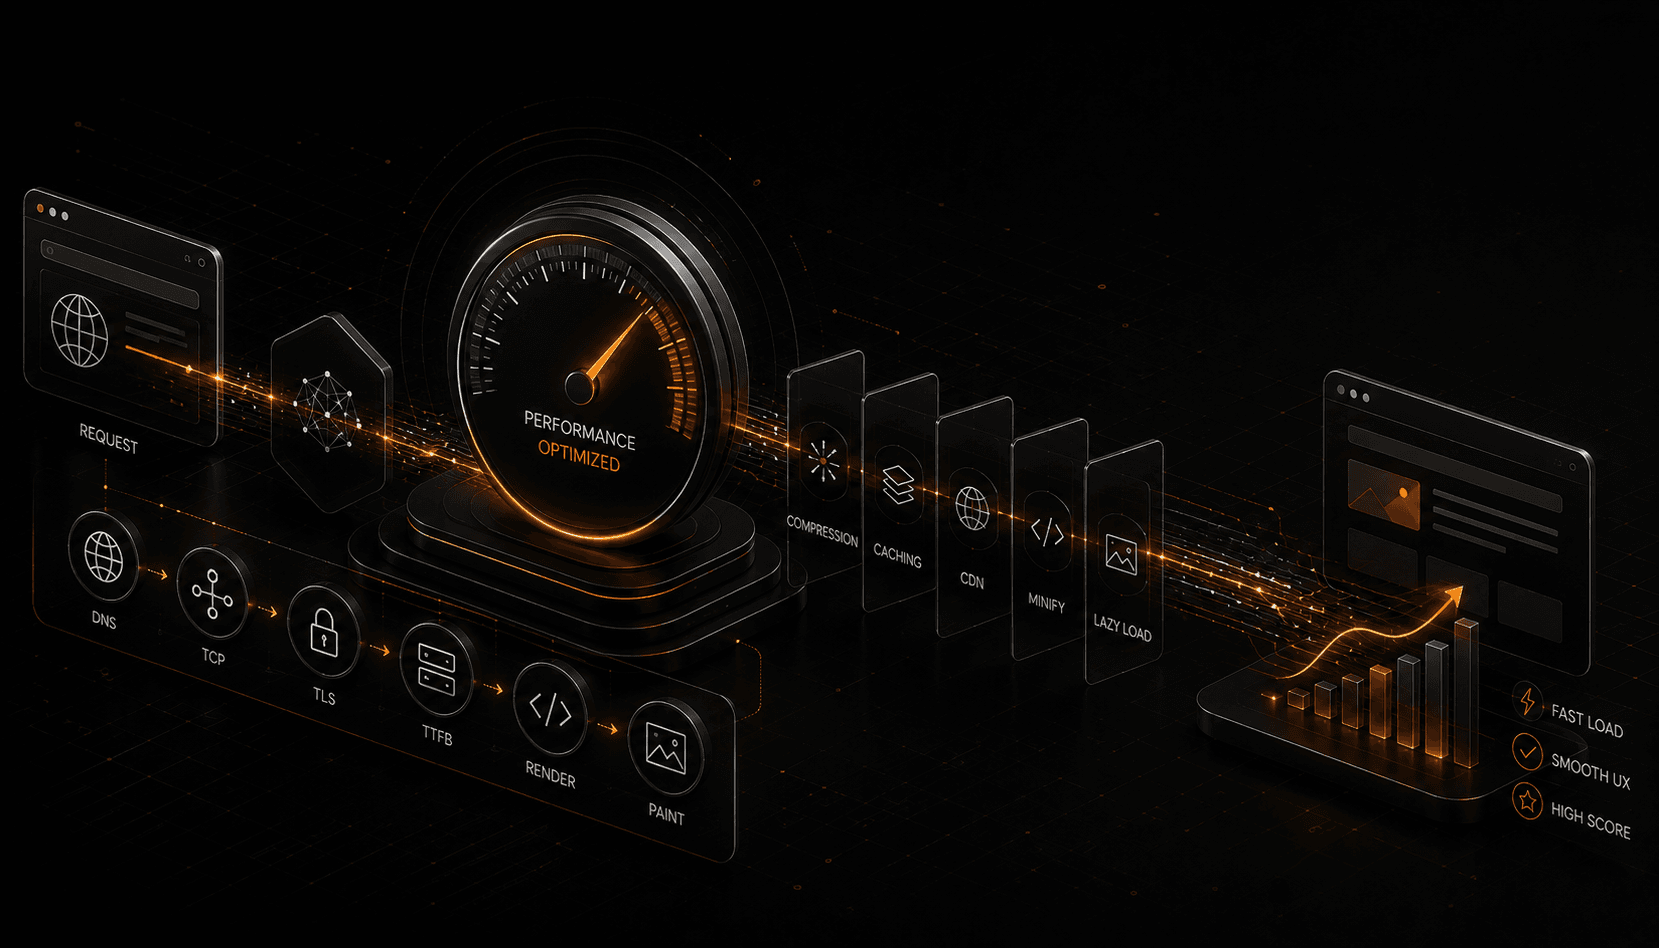
"What happens when you type a URL into a browser and press enter?" is a famous interview question, and for good reason: a complete answer touches nearly every layer of how the web works, from naming to networking to rendering. The whole sequence usually finishes in well under a second, which makes it easy to treat as a single instantaneous event. It is not. It is a precise chain of steps, and walking through it once — slowly — leaves you with a mental model you will reuse constantly. Let us follow one request end to end.
Step 1: from URL to IP address (DNS)
You typed a name — a domain like example.com — but routers move packets between numeric IP addresses, not names. So the first job is translation, and it is handled by the Domain Name System. The browser checks its own cache, then the operating system's, and if neither has the answer, it asks a DNS resolver, which works its way through the DNS hierarchy until it finds the IP address for that domain.
DNS is essentially the phone book of the internet, and like any lookup it can be cached at many levels to make it fast. It is also a common first suspect when a site is unreachable but the server is fine: if the name does not resolve, nothing else can happen.
Step 2: open a connection (TCP, then TLS)
With an IP address in hand, the browser opens a connection to the server. The classic transport is TCP, which begins with a handshake — a short back-and-forth that establishes a reliable, ordered channel between the two machines before any application data is sent.
If the URL uses https, a second handshake follows: TLS, which negotiates encryption so that everything exchanged over the connection is private and tamper-evident. The two sides agree on how to encrypt, verify the server's certificate (proving it is who it claims to be), and derive the keys for the session. Only once this completes does the actual web conversation begin — which is why an https request has slightly more setup cost than a plain one, though modern TLS is engineered to keep that overhead small.
Why the handshakes matter
The handshakes are pure setup — no page content moves during them — but they are what make the connection reliable (TCP) and private (TLS). When people talk about connection latency, this back-and-forth, multiplied by the distance to the server, is a big part of what they mean.
Step 3: the HTTP request and response
Now the browser makes its actual request using HTTP. At its core HTTP is refreshingly simple: the client sends a request line naming a method and a path, plus some headers; the server sends back a status code and a body.
GET /index.html HTTP/1.1
Host: example.com
Accept: text/html

--- the server responds ---

HTTP/1.1 200 OK
Content-Type: text/html; charset=utf-8

<!doctype html> ... the page ...
The status code is the first thing to read: codes in the 200s mean success, 300s mean redirection, 400s mean the client asked for something invalid (404 for a missing resource), and 500s mean the server itself failed. The server processes the request — often running application code and querying a database — and returns the response body, typically the HTML of the page.
Step 4: the browser renders the page
Receiving HTML is not the same as showing a page. The browser now runs its render pipeline, often called the critical rendering path:
- 1
Parse HTML into the DOM
The browser reads the markup and builds the Document Object Model — a tree of nodes representing the page's structure.
- 2
Parse CSS into the CSSOM
Stylesheets are parsed into the CSS Object Model, describing how each node should look.
- 3
Build the render tree
DOM and CSSOM are combined into a tree of what actually needs to be drawn, with styles resolved.
- 4
Layout
The browser computes the exact position and size of every element — where each box sits on the page.
- 5
Paint and composite
Finally, the pixels are drawn, layer by layer, and composited into the image you see.
Two wrinkles matter here. CSS is render-blocking — the browser will not paint until it has the styles, to avoid showing an unstyled flash — and a plain <script> tag can block parsing while it downloads and runs, which is why script placement and the async and defer attributes matter for how fast a page appears. Meanwhile the HTML often references more resources (images, fonts, more scripts), each of which can trigger its own request, sometimes reusing the connection already opened.
The whole chain, in order
Practical takeaway
The reason this question endures is that the answer is a map of the entire web stack, and the map is genuinely useful for debugging. A page that will not load at all points at DNS or the connection. A blank page that returned quickly points at a 4xx or 5xx status. A page that arrives but renders slowly points at the render pipeline — render-blocking CSS, parser-blocking scripts, or a heavy layout. Knowing the sequence turns "the site is broken" into a short list of specific, checkable stages — and that is what the next article, on web performance, builds on directly.
Sources & Further Reading
- 01An overview of HTTP — MDN Web DocsHow HTTP requests, responses, methods, and status codes work.
- 02RFC 9110 — HTTP Semantics — IETF, 2022The authoritative specification of HTTP semantics.
- 03RFC 1035 — Domain Names: Implementation and Specification — IETF, 1987The core DNS specification.
- 04RFC 8446 — The Transport Layer Security (TLS) Protocol Version 1.3 — IETF, 2018How the modern TLS handshake establishes an encrypted connection.
- 05Critical rendering path — MDN Web DocsHow the browser turns HTML and CSS into rendered pixels.
Editorial note — A conceptual explainer of the standard web request lifecycle, drawn from the relevant RFCs and MDN. No timing figures are quoted; latency is described qualitatively.